WeightedData
WeightedData[{x1,x2,…},{w1,w2,…}]
表示具有权 wi 的观察 xi.
WeightedData[{x1,x2,…},fn]
表示具有权函数 fn 的观察 xi.
更多信息
- WeightedData 对每个数据点增加具有权重的数据.
- 数据 {x1,x2,…} 和权 {w1,w2,…} 应该是等长度的列表.
- 权函数 fn 应用于列表 {x1,x2,…} 应返回权 {w1,w2,…} 的显式列表.
- 可用于统计函数的 WeightedData 包括:
-
Mean,Variance,… 描述性统计函数 EmpiricalDistribution,… 非参数分布估计 EstimatedDistribution,… 参数分布估计 - WeightedData[{x1,x2,…}] 给出具有相等权值的数据.
- WeightedData 的属性可以通过指定 WeightedData[…]["property"] 获得.
- 可使用 WeightedData[…]["Properties"] 获取可用属性的列表.
- WeightedData 具有以下属性:
-
"EmpiricalPDF" 数据值和估计的权 "InputData" 无权输入数据值 "MetaInformation" 包含元信息规则的列表 "Weights" 包含数据权的列表
范例
打开所有单元 关闭所有单元基本范例 (1)
data = {8, 3, 5, 4, 9, 0, 4, 2, 2, 3};
w = {0.15, 0.09, 0.12, 0.10, 0.16, 0., 0.11, 0.08, 0.08, 0.09};𝒜 = WeightedData[data, w]计算加权的 Mean 和 StandardDeviation:
Mean[𝒜]StandardDeviation[𝒜]范围 (10)
data = {8, 3, 5, 4, 9, 0, 4, 2, 2, 3};
w = {0.15, 0.09, 0.12, 0.10, 0.16, 0., 0.11, 0.08, 0.08, 0.09};𝒜 = WeightedData[data, w];Table[{i, i[𝒜]}, {i, {Mean, Median, Variance, StandardDeviation, Kurtosis, Skewness, InterquartileRange}}]//Gridx = {{1, 2}, {4, 5}, {5, 6}, {7, 3}};
w = {.5, .25, .1, 1};𝒜 = WeightedData[x, w]Mean[𝒜]Covariance[𝒜]Correlation[𝒜]x = RandomInteger[{1, 25}, 5000];𝒜 = Table[WeightedData[x, Function@@{t, t^i}], {i, Range[0, 4]}];N[Mean /@ 𝒜]N[Variance /@ 𝒜]Plot[Evaluate@Table[PDF[SmoothKernelDistribution[w], a], {w, 𝒜}], {a, -3, 30}, PlotRange -> All, PlotLegends -> Map[Row[{"t --> ", #}]&, t ^ Range[0, 4]]]data = RandomVariate[NormalDistribution[0, 1], 50];
w = data ^ 2;𝒜 = WeightedData[data, w]dists = Table[𝒟[𝒜], {𝒟, {EmpiricalDistribution, HistogramDistribution, SmoothKernelDistribution}}];Table[Plot[CDF[i, x], {x, -3, 3}, PlotLabel -> Row[{"Mean: ", Mean[i]}], Exclusions -> None], {i, dists}]data = RandomReal[{0, 100}, 1000];
w = PDF[ExponentialDistribution[1 / 20], #]&;𝒜 = WeightedData[data, w]𝒟1 = EstimatedDistribution[𝒜, ExponentialDistribution[a]]𝒟2 = EmpiricalDistribution[𝒜];Plot[{CDF[𝒟1, x], CDF[𝒟2, x]}, {x, 0, 50}, Exclusions -> None, PlotStyle -> {Thick, Automatic}, PlotLegends -> {"𝒟1", "𝒟2"}]从 WeightedData 对象提取输入对象:
𝒜 = WeightedData[Automatic, {{4.3424867371049345, 84.95915906432668, 54.62083275189872,
   60.351715598529864, 74.13571604649297, 60.94262726482822, 66.51118636065769, 64.48764263803247,
   71.21344855673459, 82.3471338515244, 99.98746459746363, 17.1 ... 584268284, 0.004700837378501972,
   0.008097966826215594, 0.0027249292830005016, 0.029142913216900736, 0.005685347349364164,
   0.02694522380487357, 0.013049595682933283, 0.0005752644284236291, 0.0013256312483065082,
0.0004190555990108067}}];d = 𝒜["InputData"];𝒟1 = HistogramDistribution[d];𝒟2 = HistogramDistribution[𝒜];Table[Plot[PDF[𝒟, x], {x, 0, 100}, Filling -> Axis, Exclusions -> None, PlotRange -> {0, .04}], {𝒟, {𝒟1, 𝒟2}}]从 WeightedData 对象获取权值:
𝒜 = WeightedData[Automatic, {{4.3424867371049345, 84.95915906432668, 54.62083275189872,
   60.351715598529864, 74.13571604649297, 60.94262726482822, 66.51118636065769, 64.48764263803247,
   71.21344855673459, 82.3471338515244, 99.98746459746363, 17.1 ... 584268284, 0.004700837378501972,
   0.008097966826215594, 0.0027249292830005016, 0.029142913216900736, 0.005685347349364164,
   0.02694522380487357, 0.013049595682933283, 0.0005752644284236291, 0.0013256312483065082,
0.0004190555990108067}}];w = 𝒜["Weights"];ListLinePlot[Sort@Transpose[{𝒜["InputData"], w}]]从经验 PDF 计算加权均值:
𝒜 = WeightedData[Automatic, {{4.3424867371049345, 84.95915906432668, 54.62083275189872,
   60.351715598529864, 74.13571604649297, 60.94262726482822, 66.51118636065769, 64.48764263803247,
   71.21344855673459, 82.3471338515244, 99.98746459746363, 17.1 ... 584268284, 0.004700837378501972,
   0.008097966826215594, 0.0027249292830005016, 0.029142913216900736, 0.005685347349364164,
   0.02694522380487357, 0.013049595682933283, 0.0005752644284236291, 0.0013256312483065082,
0.0004190555990108067}}];{d, pdf} = 𝒜["EmpiricalPDF"];d.pdf加权均值可以使用 Mean 直接计算:
Mean[𝒜]求不规则采样 TimeSeries 的加权平均值:
ts = TimeSeries[Table[{t, 2t + RandomVariate[NormalDistribution[0, 0.3]]}, {t, {0., 0.15, 0.2, 0.5, 0.75, 1., 1.5, 2}}]]wm = Mean[WeightedData[ts]]vm = Mean[ts]ListLinePlot[ts, Frame -> True, PlotMarkers -> {Automatic, Tiny},
GridLines -> {None, {{vm, Dashed}, {wm, Dotted}}},
FrameTicks -> {{Automatic, {{vm, " value mean"}, {wm, " weighted mean"}}}, {Automatic, Automatic}}]data = Quantity[{7, 3, 5, 4, 9, 0, 4, 2, 2, 3}, "Meters"];
w = {0.12, 0.09, 0.12, 0.10, 0.16, 0., 0.11, 0.08, 0.08, 0.09};𝒜 = WeightedData[data, w];Table[{i, i[𝒜]}, {i, {Mean, Median, Variance, StandardDeviation, Kurtosis, Skewness, InterquartileRange}}]//TableForm应用 (2)
data = RandomReal[{-5, 5}, 10 ^ 4];𝒜 = WeightedData[data, PDF[NormalDistribution[], #]&];𝒟 = HistogramDistribution[𝒜, 50];m = Mean[𝒜];
sd = StandardDeviation[𝒜];
Plot[PDF[𝒟, x], {x, -4, 4}, Exclusions -> None, Filling -> Axis, Epilog -> Inset[TableForm[{{"Mean:", m}, {"SD:", sd}}], {Right, Top}, {Right, Top}]]BlockRandom[SeedRandom[40];
data = RandomVariate[WeibullDistribution[2.3, 0.8], 30]];mleP = {α, β} /. FindDistributionParameters[data, WeibullDistribution[α, β]]通过重复来自于带有单位参数的 DirichletDistribution 的带有加权样本的权重估计应用分数随机权重引导来估计置信区间:
weightSample[n_Integer] := RandomVariate[DirichletDistribution[ConstantArray[1, n + 1]]]frwData[data_] := WeightedData[data, weightSample[Length[data]]]frwPs = Table[{α, β} /. FindDistributionParameters[frwData[data], WeibullDistribution[α, β]], 1000];ListPlot[frwPs, Epilog -> {Directive[PointSize[Large], Orange], Point[mleP]}]EstimatedDistribution[frwPs, BinormalDistribution[{αμ, βm}, {αv, βv}, ρ]]属性和关系 (3)
权重相同的 WeightedData:
data = {8, 3, 5, 4, 9, 0, 4, 2, 2, 3};
wd = WeightedData[data]EmpiricalDistribution[data] === EmpiricalDistribution[wd]描述性统计量基于基本的 EmpiricalDistribution:
𝒜 = WeightedData[{{-30, -30}, {10, 10}, {20, 20}}, {1, 7, 2}];𝒟 = EmpiricalDistribution[𝒜];{Mean[𝒜], Mean[𝒟]}{Variance[𝒜], Variance[𝒟]}WeightedData 可用于 TimeSeries 对象:
ts = TimeSeries[vals = {x1, x2, x3, x4}, {times = {0, 1 / 3, 1 / 2, 1}}];
wm = Mean[WeightedData[ts]]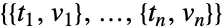
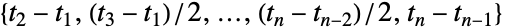
weights = MovingAverage[ArrayPad[Differences[times], {1, 1}, "Fixed"], 2]Normalize[weights, Total].valsevals = ArrayPad[vals, {1, 1}, "Fixed"]etimes = ArrayPad[times, {1, 1}, "ReflectedDifferences"]if = Interpolation[Transpose[{etimes, evals}], InterpolationOrder -> 1];{tmin, tmax} = {Mean[Take[etimes, 2]], Mean[Take[etimes, -2]]}(1/tmax - tmin)Integrate[if[t], {t, tmin, tmax}]//Expand文本
Wolfram Research (2012),WeightedData,Wolfram 语言函数,https://reference.wolfram.com/language/ref/WeightedData.html.
CMS
Wolfram 语言. 2012. "WeightedData." Wolfram 语言与系统参考资料中心. Wolfram Research. https://reference.wolfram.com/language/ref/WeightedData.html.
APA
Wolfram 语言. (2012). WeightedData. Wolfram 语言与系统参考资料中心. 追溯自 https://reference.wolfram.com/language/ref/WeightedData.html 年